Attention Is All You Need
Introduction
Recurrent neural networks, long short-term memory and gated recurrent neural networks in particular, have been firmly established as state of the art approaches in sequence modeling and transduction problems such as language modeling and machine translationBefore this paper landed in 2017, if you wanted a model to read or translate text, you reached for a recurrent network — an LSTM or a GRU. They'd been the workhorses of the field for years, and they were genuinely good at their jobs. . Numerous efforts have since continued to push the boundaries of recurrent language models and encoder-decoder architectures .
Recurrent models typically factor computation along the symbol positions of the input and output sequences. Aligning the positions to steps in computation time, they generate a sequence of hidden states \(h_t\), as a function of the previous hidden state \(h_{t-1}\) and the input for position \(t\). This inherently sequential nature precludes parallelization within training examples, which becomes critical at longer sequence lengths, as memory constraints limit batching across examples.But recurrent networks had a fundamental problem: they read a sentence strictly word-by-word. Word 1, then word 2, then word 3. Each step had to wait for the one before. Even with a hundred GPUs sitting idle, you couldn't speed training up within a single sentence. And the longer the sentence, the more this hurt. Recent work has achieved significant improvements in computational efficiency through factorization tricks and conditional computation , while also improving model performance in case of the latter. The fundamental constraint of sequential computation, however, remains.
Attention mechanisms have become an integral part of compelling sequence modeling and transduction models in various tasks, allowing modeling of dependencies without regard to their distance in the input or output sequences . In all but a few cases , however, such attention mechanisms are used in conjunction with a recurrent network.
In this work we propose the Transformer, a model architecture eschewing recurrence and instead relying entirely on an attention mechanism to draw global dependencies between input and output.The authors did something bold: they threw recurrence out entirely. The Transformer reads every word at once, in parallel, and uses a mechanism called *attention* — a way for each word to look directly at every other word — to handle the relationships between them. The Transformer allows for significantly more parallelization and can reach a new state of the art in translation quality after being trained for as little as twelve hours on eight P100 GPUs.That one change made training dramatically faster. On eight GPUs, a fresh Transformer reached a *new* state of the art for translation in roughly twelve hours. The previous best translation models took days or weeks on bigger hardware.
Background
The goal of reducing sequential computation also forms the foundation of the Extended Neural GPU , ByteNet and ConvS2S , all of which use convolutional neural networks as basic building block, computing hidden representations in parallel for all input and output positions. In these models, the number of operations required to relate signals from two arbitrary input or output positions grows in the distance between positions, linearly for ConvS2S and logarithmically for ByteNet. This makes it more difficult to learn dependencies between distant positionsEarlier attempts to replace RNNs — like ByteNet and ConvS2S — used convolutions instead. Those parallelized nicely, but they inherited a different problem: it took more compute to relate two words the further apart they were. Connecting the first word of a long sentence to the last was genuinely hard. The Transformer's attention fixes this — the cost of relating word 1 to word 500 is the same as relating word 1 to word 2. . In the Transformer this is reduced to a constant number of operations, albeit at the cost of reduced effective resolution due to averaging attention-weighted positions, an effect we counteract with Multi-Head Attention as described in section 3.2.
Self-attention, sometimes called intra-attention is an attention mechanism relating different positions of a single sequence in order to compute a representation of the sequence. Self-attention has been used successfully in a variety of tasks including reading comprehension, abstractive summarization, textual entailment and learning task-independent sentence representations .
End-to-end memory networks are based on a recurrent attention mechanism instead of sequence-aligned recurrence and have been shown to perform well on simple-language question answering and language modeling tasks .
To the best of our knowledge, however, the Transformer is the first transduction model relying entirely on self-attention to compute representations of its input and output without using sequence-aligned RNNs or convolution. In the following sections, we will describe the Transformer, motivate self-attention and discuss its advantages over models such as and .
Model Architecture
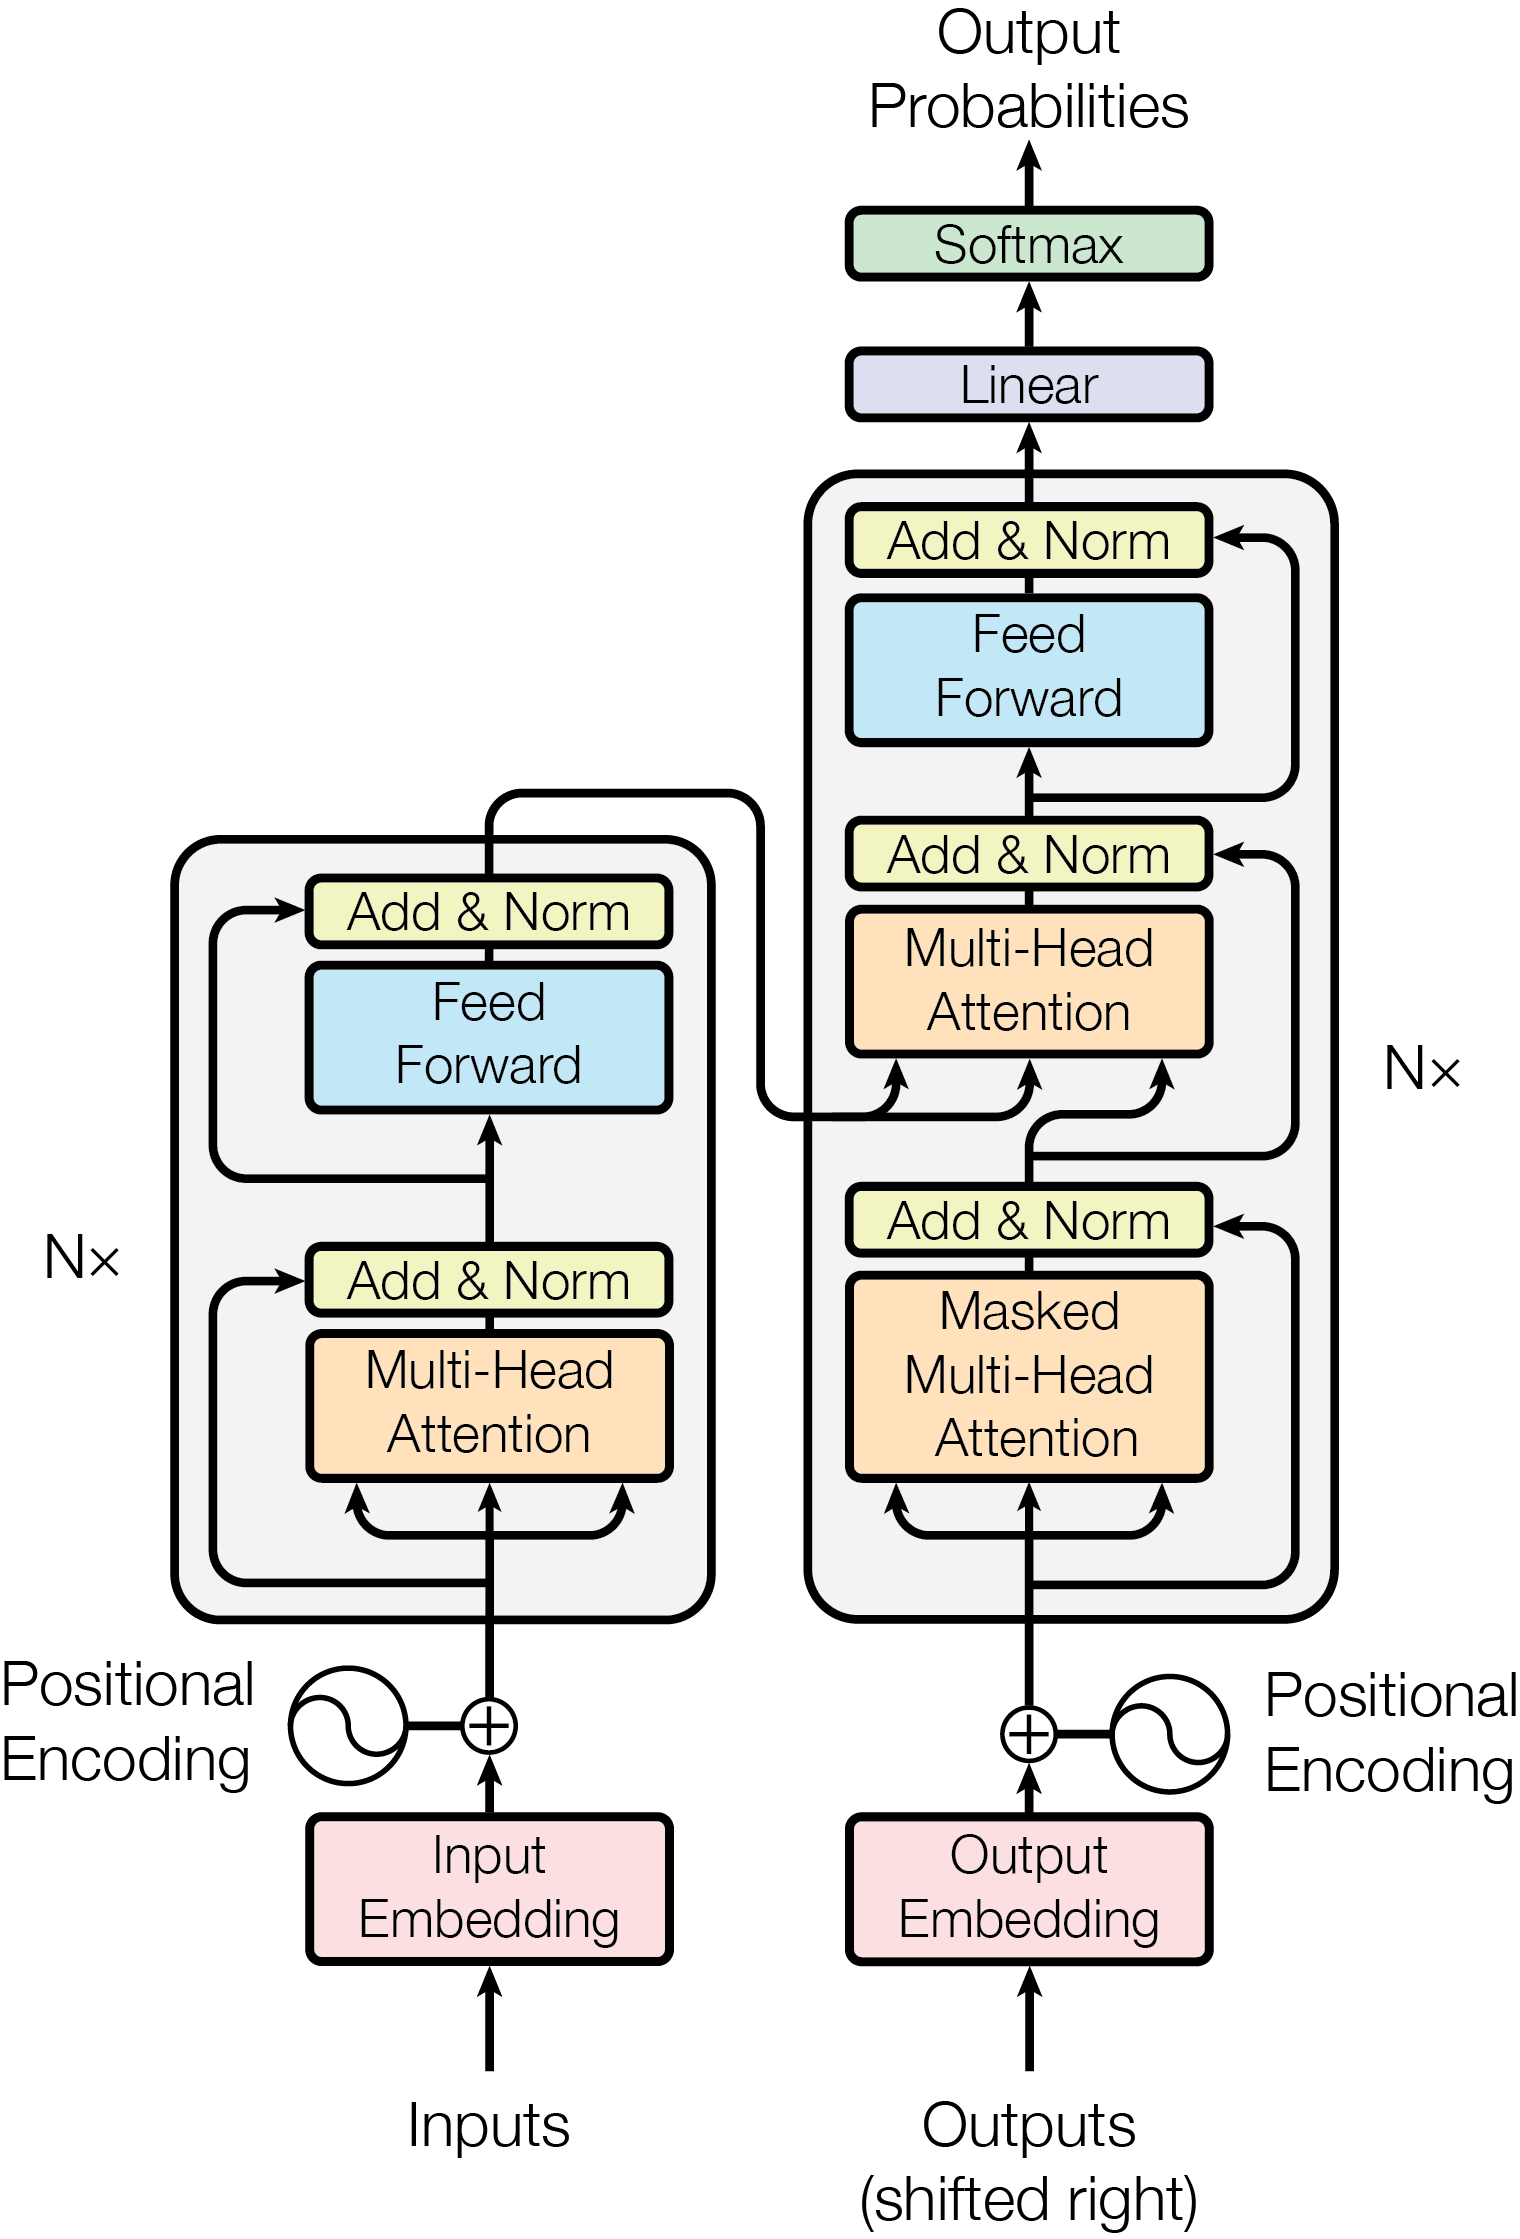
Most competitive neural sequence transduction models have an encoder-decoder structure . Here, the encoder maps an input sequence of symbol representations \((x_1, ..., x_n)\) to a sequence of continuous representations \(\mathbf{z} = (z_1, ..., z_n)\). Given \(\mathbf{z}\), the decoder then generates an output sequence \((y_1,...,y_m)\) of symbols one element at a time. At each step the model is auto-regressive , consuming the previously generated symbols as additional input when generating the next.
The Transformer follows this overall architecture using stacked self-attention and point-wise, fully connected layers for both the encoder and decoder, shown in the left and right halves of Figure 1, respectively.
Encoder and Decoder Stacks
Encoder:
The encoder is composed of a stack of \(N=6\) identical layers. Each layer has two sub-layers. The first is a multi-head self-attention mechanism, and the second is a simple, position-wise fully connected feed-forward network.The encoder — the half of the model that reads the input — is six identical blocks in a stack. Each block does two things in order: first every word attends to every other word (self-attention), then each word's vector is passed through a small neural network (the feed-forward layer). Residual “skip” connections wrap around each step, so the raw information can always pass through unchanged if the block doesn't want to modify it. We employ a residual connection around each of the two sub-layers, followed by layer normalization . That is, the output of each sub-layer is \(\mathrm{LayerNorm}(x + \mathrm{Sublayer}(x))\), where \(\mathrm{Sublayer}(x)\) is the function implemented by the sub-layer itself. To facilitate these residual connections, all sub-layers in the model, as well as the embedding layers, produce outputs of dimension \(d_{\text{model}}=512\).
Decoder:
The decoder is also composed of a stack of \(N=6\) identical layers. In addition to the two sub-layers in each encoder layer, the decoder inserts a third sub-layer, which performs multi-head attention over the output of the encoder stack. Similar to the encoder, we employ residual connections around each of the sub-layers, followed by layer normalization. We also modify the self-attention sub-layer in the decoder stack to prevent positions from attending to subsequent positions.The decoder — the half that generates the translation — has an important twist. When it's deciding what word to produce next, we hide the future: it's not allowed to peek at words it hasn't produced yet. This is enforced by zeroing out the attention scores for later positions, so the model literally cannot see them. This masking, combined with fact that the output embeddings are offset by one position, ensures that the predictions for position \(i\) can depend only on the known outputs at positions less than \(i\).
Attention
An attention function can be described as mapping a query and a set of key-value pairs to an output, where the query, keys, values, and output are all vectors. The output is computed as a weighted sum of the values, where the weight assigned to each value is computed by a compatibility function of the query with the corresponding key.
Scaled Dot-Product Attention
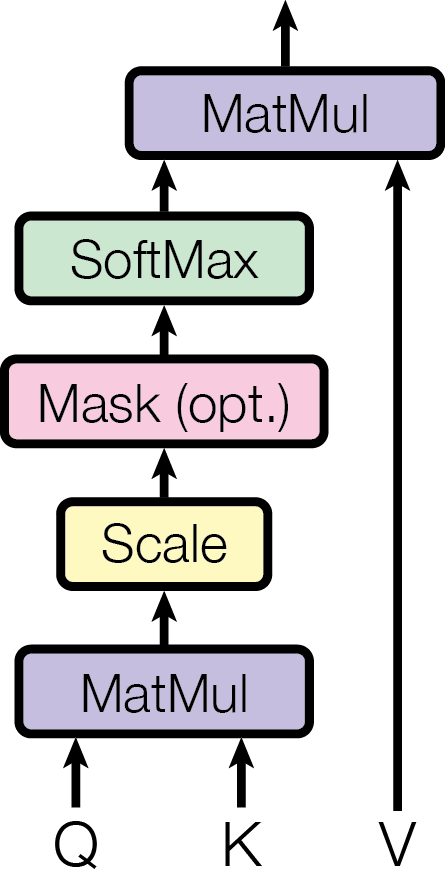
We call our particular attention "Scaled Dot-Product Attention" (Figure 2). The input consists of queries and keys of dimension \(d_k\), and values of dimension \(d_v\). We compute the dot products of the query with all keys, divide each by \(\sqrt{d_k}\), and apply a softmax function to obtain the weights on the values.Here's what attention actually does, in three concrete steps. Each word is projected into three vectors: a *query* (“what am I looking for?”), a *key* (“what do I represent?”), and a *value* (“what do I contribute?”). (1) To compute attention for the word “the,” you take its query and dot-product it against every other word's key — the bigger the dot product, the more relevant. (2) Divide by √d_k, run through softmax, and now the scores sum to 1 — you've got a probability distribution over every word. (3) Use those probabilities to take a weighted average of the other words' values. That average is “the”'s new vector. Intuition: if “the” is looking for its antecedent in “the cat sat,” its query lines up strongly with “cat”'s key — so “the” ends up mostly mixing in “cat”'s value.
In practice, we compute the attention function on a set of queries simultaneously, packed together into a matrix \(Q\). The keys and values are also packed together into matrices \(K\) and \(V\). We compute the matrix of outputs as:
\[\begin{equation} \mathrm{Attention}(Q, K, V) = \mathrm{softmax}(\frac{QK^T}{\sqrt{d_k}})V \end{equation}\]
The two most commonly used attention functions are additive attention , and dot-product (multiplicative) attention. Dot-product attention is identical to our algorithm, except for the scaling factor of \(\frac{1}{\sqrt{d_k}}\). Additive attention computes the compatibility function using a feed-forward network with a single hidden layer. While the two are similar in theoretical complexity, dot-product attention is much faster and more space-efficient in practice, since it can be implemented using highly optimized matrix multiplication code.
While for small values of \(d_k\) the two mechanisms perform similarly, additive attention outperforms dot product attention without scaling for larger values of \(d_k\) . We suspect that for large values of \(d_k\), the dot products grow large in magnitude, pushing the softmax function into regions where it has extremely small gradientsWhy divide the scores by √d_k? When the key vectors are high-dimensional (say d_k = 64), the raw dot products tend to come out *large in magnitude*. Large scores push softmax into a saturated regime where one score dominates and the gradients become nearly zero — so nothing can learn. Dividing by √d_k (so √64 = 8) shrinks the scores back into a range where softmax still has usable gradients. A small fix, but without it this architecture wouldn't train. 1. To counteract this effect, we scale the dot products by \(\frac{1}{\sqrt{d_k}}\).
Multi-Head Attention
Scaled Dot-Product Attention
Multi-Head Attention
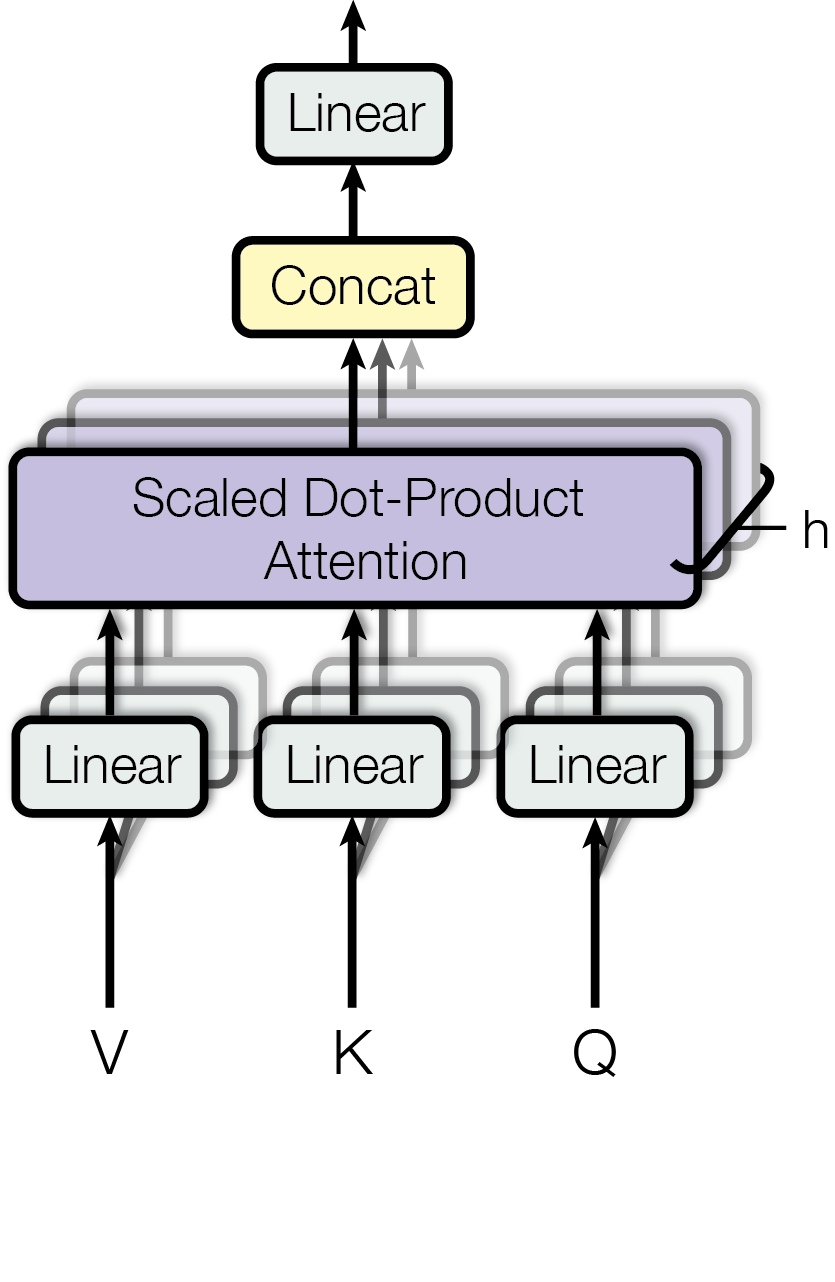
Instead of performing a single attention function with \(d_{\text{model}}\)-dimensional keys, values and queries, we found it beneficial to linearly project the queries, keys and values \(h\) times with different, learned linear projections to \(d_k\), \(d_k\) and \(d_v\) dimensions, respectively. On each of these projected versions of queries, keys and values we then perform the attention function in parallel, yielding \(d_v\)-dimensional output values. These are concatenated and once again projected, resulting in the final values, as depicted in Figure 2.
Multi-head attention allows the model to jointly attend to information from different representation subspaces at different positions. With a single attention head, averaging inhibits this.Rather than running one big attention operation, the Transformer runs eight smaller ones *in parallel* — these are the “heads” — and stitches them together. Why? Because any single attention head has to pick *one* pattern of what-looks-at-what. With eight heads, the model can learn eight different patterns at once: maybe one head tracks subject-verb agreement, another tracks the noun a pronoun refers to, another captures topic or tone. One head alone would have to mash all of these patterns into a single fuzzy signal.
\[\begin{align*} \mathrm{MultiHead}(Q, K, V) &= \mathrm{Concat}(\mathrm{head_1}, ..., \mathrm{head_h})W^O\\ % \mathrm{where} \mathrm{head_i} &= \mathrm{Attention}(QW_Q_i^{\dmodel \times d_q}, KW_K_i^{\dmodel \times d_k}, VW^V_i^{\dmodel \times d_v})\\ \text{where}~\mathrm{head_i} &= \mathrm{Attention}(QW^Q_i, KW^K_i, VW^V_i)\\ \end{align*}\]
Where the projections are parameter matrices \(W^Q_i \in \mathbb{R}^{d_{\text{model}}\times d_k}\), \(W^K_i \in \mathbb{R}^{d_{\text{model}}\times d_k}\), \(W^V_i \in \mathbb{R}^{d_{\text{model}}\times d_v}\) and \(W^O \in \mathbb{R}^{hd_v \times d_{\text{model}}}\).
In this work we employ \(h=8\) parallel attention layers, or heads. For each of these we use \(d_k=d_v=d_{\text{model}}/h=64\).Concretely: eight heads, each working on a 64-dimensional slice of the 512-dimensional representation (8 × 64 = 512). So the total compute is roughly the same as running a single head at the full 512 dimensions — but now you get eight independent attention patterns instead of one averaged one. A nice trade. Due to the reduced dimension of each head, the total computational cost is similar to that of single-head attention with full dimensionality.
Applications of Attention in our Model
The Transformer uses multi-head attention in three different ways:
In "encoder-decoder attention" layers, the queries come from the previous decoder layer, and the memory keys and values come from the output of the encoder. This allows every position in the decoder to attend over all positions in the input sequence. This mimics the typical encoder-decoder attention mechanisms in sequence-to-sequence models such as .
The encoder contains self-attention layers. In a self-attention layer all of the keys, values and queries come from the same place, in this case, the output of the previous layer in the encoder. Each position in the encoder can attend to all positions in the previous layer of the encoder.
Similarly, self-attention layers in the decoder allow each position in the decoder to attend to all positions in the decoder up to and including that position. We need to prevent leftward information flow in the decoder to preserve the auto-regressive property. We implement this inside of scaled dot-product attention by masking out (setting to \(-\infty\)) all values in the input of the softmax which correspond to illegal connections. See Figure 2.
Position-wise Feed-Forward Networks
In addition to attention sub-layers, each of the layers in our encoder and decoder contains a fully connected feed-forward network, which is applied to each position separately and identically. This consists of two linear transformations with a ReLU activation in between.
\[\begin{equation} \mathrm{FFN}(x)=\max(0, xW_1 + b_1) W_2 + b_2 \end{equation}\]
While the linear transformations are the same across different positions, they use different parameters from layer to layer. Another way of describing this is as two convolutions with kernel size 1. The dimensionality of input and output is \(d_{\text{model}}=512\), and the inner-layer has dimensionality \(d_{ff}=2048\).
Embeddings and Softmax
Similarly to other sequence transduction models, we use learned embeddings to convert the input tokens and output tokens to vectors of dimension \(d_{\text{model}}\). We also use the usual learned linear transformation and softmax function to convert the decoder output to predicted next-token probabilities. In our model, we share the same weight matrix between the two embedding layers and the pre-softmax linear transformation, similar to . In the embedding layers, we multiply those weights by \(\sqrt{d_{\text{model}}}\).
Positional Encoding
Since our model contains no recurrence and no convolution, in order for the model to make use of the order of the sequence, we must inject some information about the relative or absolute position of the tokens in the sequence. To this end, we add "positional encodings" to the input embeddings at the bottoms of the encoder and decoder stacks.Here's a subtle problem with pure attention: it has no idea what order the words came in. To an attention layer, “dog bites man” and “man bites dog” look the same — just a set of three tokens. To fix this, the authors add a *position signal* to each word's embedding before the model sees it: a vector whose value depends on where the word sits in the sentence. The specific signal they chose was a mix of sines and cosines at different frequencies — think of a clock with multiple hands, each rotating at its own speed. The positional encodings have the same dimension \(d_{\text{model}}\) as the embeddings, so that the two can be summed. There are many choices of positional encodings, learned and fixed .
In this work, we use sine and cosine functions of different frequencies:
\[\begin{align*} PE_{(pos,2i)} = sin(pos / 10000^{2i/d_{\text{model}}}) \\ PE_{(pos,2i+1)} = cos(pos / 10000^{2i/d_{\text{model}}}) \end{align*}\]
where \(pos\) is the position and \(i\) is the dimension. That is, each dimension of the positional encoding corresponds to a sinusoid. The wavelengths form a geometric progression from \(2\pi\) to \(10000 \cdot 2\pi\). We chose this function because we hypothesized it would allow the model to easily learn to attend by relative positions, since for any fixed offset \(k\), \(PE_{pos+k}\) can be represented as a linear function of \(PE_{pos}\).
We also experimented with using learned positional embeddings instead, and found that the two versions produced nearly identical results (see Table 3 row (E)). We chose the sinusoidal version because it may allow the model to extrapolate to sequence lengths longer than the ones encountered during training.Why sinusoids specifically? The authors argued: a learned position embedding (one vector per position) runs out the moment you hit a sentence longer than anything in training. But a sinusoidal pattern extends forever, so *in principle* the model should cope with sentences longer than it has ever seen. They hedged this with “may allow” — they weren't sure it would actually work, but it was the cleanest theoretical argument.
Why Self-Attention
In this section we compare various aspects of self-attention layers to the recurrent and convolutional layers commonly used for mapping one variable-length sequence of symbol representations \((x_1, ..., x_n)\) to another sequence of equal length \((z_1, ..., z_n)\), with \(x_i, z_i \in \mathbb{R}^d\), such as a hidden layer in a typical sequence transduction encoder or decoder. Motivating our use of self-attention we consider three desiderata.
One is the total computational complexity per layer. Another is the amount of computation that can be parallelized, as measured by the minimum number of sequential operations required.
The third is the path length between long-range dependencies in the network. Learning long-range dependencies is a key challenge in many sequence transduction tasks. One key factor affecting the ability to learn such dependencies is the length of the paths forward and backward signals have to traverse in the network. The shorter these paths between any combination of positions in the input and output sequences, the easier it is to learn long-range dependencies . Hence we also compare the maximum path length between any two input and output positions in networks composed of the different layer types.
| Layer Type | Complexity per Layer | Sequential | Maximum Path Length |
| Operations | |||
| Self-Attention | \(O(n^2 \cdot d)\) | \(O(1)\) | \(O(1)\) |
| Recurrent | \(O(n \cdot d^2)\) | \(O(n)\) | \(O(n)\) |
| Convolutional | \(O(k \cdot n \cdot d^2)\) | \(O(1)\) | \(O(log_k(n))\) |
| Self-Attention (restricted) | \(O(r \cdot n \cdot d)\) | \(O(1)\) | \(O(n/r)\) |
As noted in Table 1, a self-attention layer connects all positions with a constant number of sequentially executed operations, whereas a recurrent layer requires \(O(n)\) sequential operations.Compare how long it takes to connect two words. An RNN reading “The cat that the dog chased was black” has to process every word between “cat” and “black” sequentially before the signal from one can reach the other. Self-attention connects them in a single step — “cat” can look at “black” directly, no matter how many words are in between. On a GPU that can run many operations at once, this difference is huge. In terms of computational complexity, self-attention layers are faster than recurrent layers when the sequence length \(n\) is smaller than the representation dimensionality \(d\), which is most often the case with sentence representations used by state-of-the-art models in machine translations,There's a second win on top of the parallelism. For typical translation sentence lengths (tens of words, much smaller than the 512-dimensional representation), the total compute inside a self-attention layer is actually *lower* than inside a recurrent layer of the same size. So self-attention isn't just easier to parallelize — it's often cheaper in absolute terms. such as word-piece and byte-pair representations. To improve computational performance for tasks involving very long sequences, self-attention could be restricted to considering only a neighborhood of size \(r\) in the input sequence centered around the respective output position. This would increase the maximum path length to \(O(n/r)\). We plan to investigate this approach further in future work.
A single convolutional layer with kernel width \(k < n\) does not connect all pairs of input and output positions. Doing so requires a stack of \(O(n/k)\) convolutional layers in the case of contiguous kernels, or \(O(log_k(n))\) in the case of dilated convolutions , increasing the length of the longest paths between any two positions in the network. Convolutional layers are generally more expensive than recurrent layers, by a factor of \(k\). Separable convolutions , however, decrease the complexity considerably, to \(O(k \cdot n \cdot d + n \cdot d^2)\). Even with \(k=n\), however, the complexity of a separable convolution is equal to the combination of a self-attention layer and a point-wise feed-forward layer, the approach we take in our model.
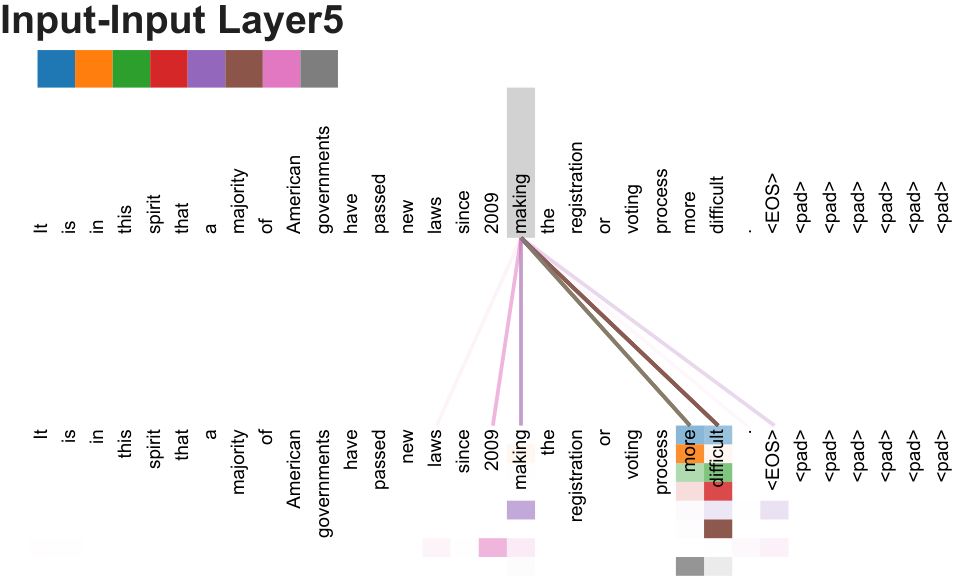
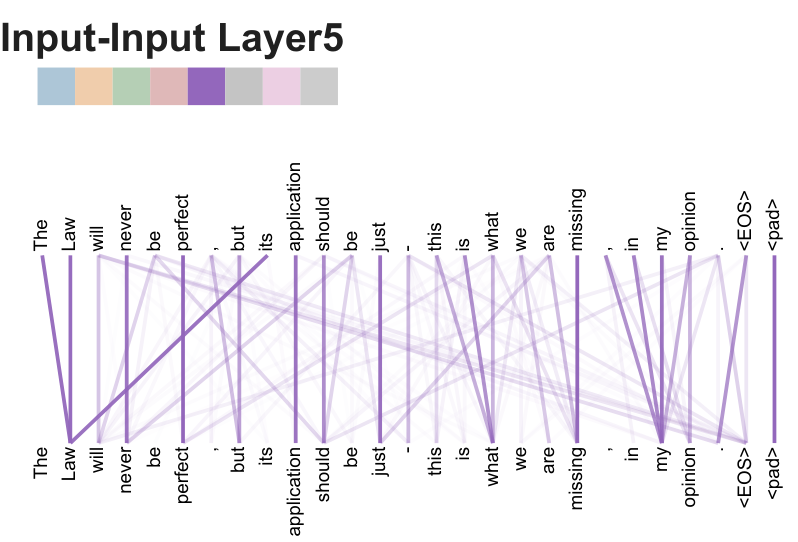
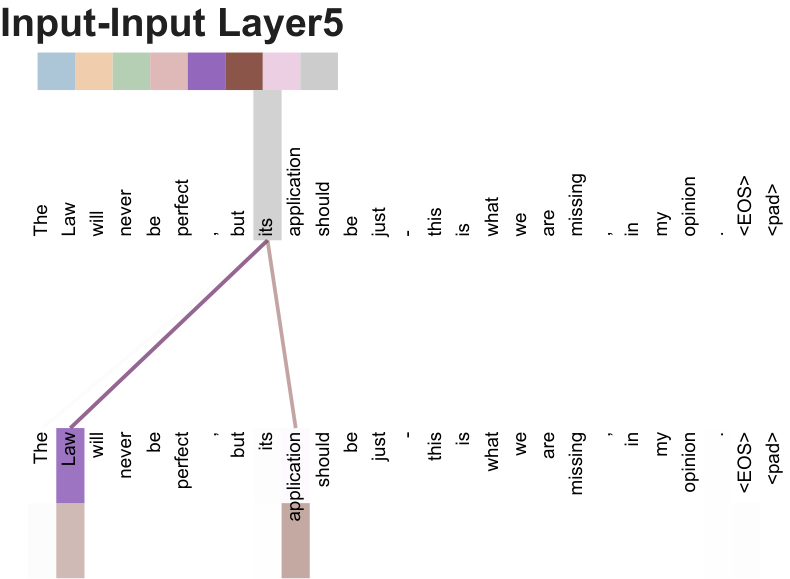
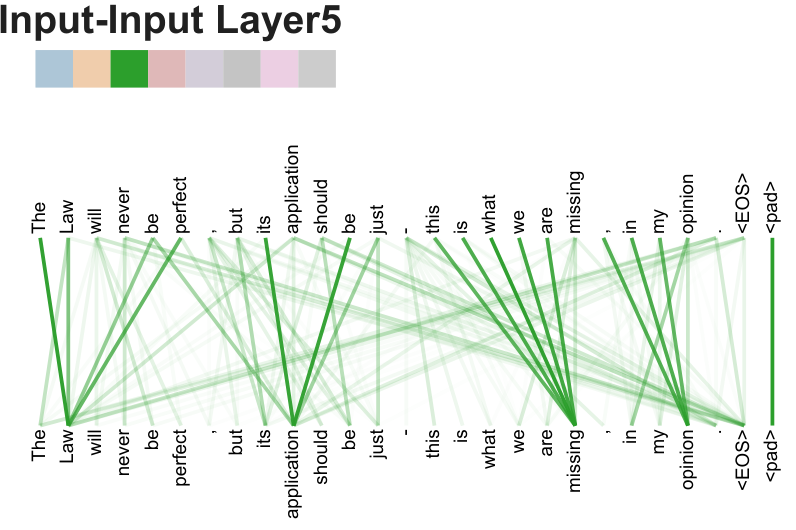
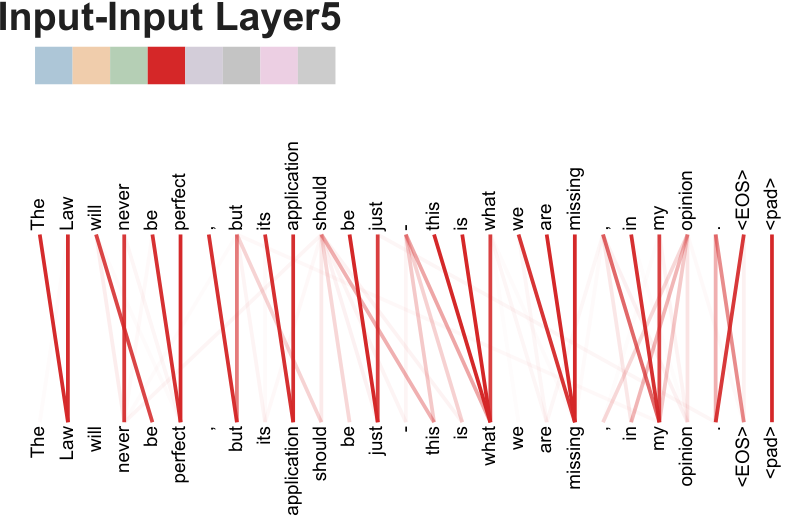
As side benefit, self-attention could yield more interpretable models. We inspect attention distributions from our models and present and discuss examples in the appendix.A third, quieter benefit: you can *see* what the model is doing. Each head's attention pattern is a matrix of soft weights — you can plot it as a heatmap. When the authors looked, individual heads had clearly specialized: one head seemed to track which word each pronoun refers to; another attended strongly from verbs to their direct objects. The model was rediscovering the shape of grammar without being told it existed. Not only do individual attention heads clearly learn to perform different tasks, many appear to exhibit behavior related to the syntactic and semantic structure of the sentences.
Training
This section describes the training regime for our models.
Training Data and Batching
We trained on the standard WMT 2014 English-German dataset consisting of about 4.5 million sentence pairs.Training data was the standard WMT 2014 corpora — English-German (4.5 million sentence pairs) and English-French (36 million). Sentences were tokenized into byte-pair or word-piece units so that rare words get broken into reusable sub-pieces (so “unbelievable” might become “un-believ-able,” letting the model handle words it's never seen as a whole). Sentences were encoded using byte-pair encoding , which has a shared source-target vocabulary of about 37000 tokens. For English-French, we used the significantly larger WMT 2014 English-French dataset consisting of 36M sentences and split tokens into a 32000 word-piece vocabulary . Sentence pairs were batched together by approximate sequence length. Each training batch contained a set of sentence pairs containing approximately 25000 source tokens and 25000 target tokens.
Hardware and Schedule
We trained our models on one machine with 8 NVIDIA P100 GPUs. For our base models using the hyperparameters described throughout the paper, each training step took about 0.4 seconds. We trained the base models for a total of 100,000 steps or 12 hours. For our big models,(described on the bottom line of table 3), step time was 1.0 seconds. The big models were trained for 300,000 steps (3.5 days).
Optimizer
We used the Adam optimizerThe optimizer was Adam with fairly standard settings. The learning rate did something clever though: it *warmed up* linearly over the first 4,000 steps (starting tiny, growing steadily), then decayed as 1/√step after that. Think of it as an accelerator pedal that's eased into before it settles. Warmup is now standard practice for training large Transformers; this paper helped establish the recipe. with \(\beta_1=0.9\), \(\beta_2=0.98\) and \(\epsilon=10^{-9}\). We varied the learning rate over the course of training, according to the formula:
\[\begin{equation} lrate = d_{\text{model}}^{-0.5} \cdot \min({step\_num}^{-0.5}, {step\_num} \cdot {warmup\_steps}^{-1.5}) \end{equation}\]
This corresponds to increasing the learning rate linearly for the first \(warmup\_steps\) training steps, and decreasing it thereafter proportionally to the inverse square root of the step number. We used \(warmup\_steps=4000\).
Regularization
We employ three types of regularization during training:
Residual Dropout
We apply dropout to the output of each sub-layer, before it is added to the sub-layer input and normalized. In addition, we apply dropout to the sums of the embeddings and the positional encodings in both the encoder and decoder stacks. For the base model, we use a rate of \(P_{drop}=0.1\).
Label Smoothing
During training, we employed label smoothing of value \(\epsilon_{ls}=0.1\) . This hurts perplexity, as the model learns to be more unsure, but improves accuracy and BLEU score.
Results
Machine Translation
| Model | BLEU | Training Cost (FLOPs) | |||
|---|---|---|---|---|---|
| 2-3 | EN-DE | EN-FR | EN-DE | EN-FR | |
| ByteNet | 23.75 | ||||
| Deep-Att + PosUnk | 39.2 | \(1.0\cdot10^{20}\) | |||
| GNMT + RL | 24.6 | 39.92 | \(2.3\cdot10^{19}\) | \(1.4\cdot10^{20}\) | |
| ConvS2S | 25.16 | 40.46 | \(9.6\cdot10^{18}\) | \(1.5\cdot10^{20}\) | |
| MoE | 26.03 | 40.56 | \(2.0\cdot10^{19}\) | \(1.2\cdot10^{20}\) | |
| Deep-Att + PosUnk Ensemble | 40.4 | \(8.0\cdot10^{20}\) | |||
| GNMT + RL Ensemble | 26.30 | 41.16 | \(1.8\cdot10^{20}\) | \(1.1\cdot10^{21}\) | |
| ConvS2S Ensemble | 26.36 | 41.29 | \(7.7\cdot10^{19}\) | \(1.2\cdot10^{21}\) | |
| Transformer (base model) | 27.3 | 38.1 | \(3.3\cdot10^{18}\) | ||
| Transformer (big) | 28.4 | 41.8 | \(2.3\cdot10^{19}\) | ||
On the WMT 2014 English-to-German translation task, the big transformer model (Transformer (big) in Table 2) outperforms the best previously reported models (including ensembles) by more than \(2.0\) BLEU, establishing a new state-of-the-art BLEU score of \(28.4\).The headline result. On English→German translation, the big Transformer beat every prior system — including *ensembles*, which combine multiple models and usually have a big advantage — by more than 2 BLEU points. BLEU 28.4. That was the new state of the art. The configuration of this model is listed in the bottom line of Table 3. Training took \(3.5\) days on \(8\) P100 GPUs.And it took just 3.5 days on 8 GPUs to get there. The previous state-of-the-art model had trained on dozens of GPUs for weeks. Training cost wasn't just a little better — it was roughly an order of magnitude less. Even our base model surpasses all previously published models and ensembles, at a fraction of the training cost of any of the competitive models.
On the WMT 2014 English-to-French translation task, our big model achieves a BLEU score of \(41.0\), outperforming all of the previously published single models, at less than \(1/4\) the training cost of the previous state-of-the-art model.On English→French (the other standard benchmark), the big Transformer scored 41.0 BLEU — beating every previously published *single* model (non-ensemble), at less than a quarter of the compute the previous leader had used. The Transformer (big) model trained for English-to-French used dropout rate \(P_{drop}=0.1\), instead of \(0.3\).
For the base models, we used a single model obtained by averaging the last 5 checkpoints, which were written at 10-minute intervals. For the big models, we averaged the last 20 checkpoints. We used beam search with a beam size of \(4\) and length penalty \(\alpha=0.6\) . These hyperparameters were chosen after experimentation on the development set. We set the maximum output length during inference to input length + \(50\), but terminate early when possible .
Table 2 summarizes our results and compares our translation quality and training costs to other model architectures from the literature. We estimate the number of floating point operations used to train a model by multiplying the training time, the number of GPUs used, and an estimate of the sustained single-precision floating-point capacity of each GPU 2.
Model Variations
| \(N\) | \(d_{\text{model}}\) | \(d_{\text{ff}}\) | \(h\) | \(d_k\) | \(d_v\) | \(P_{drop}\) | \(\epsilon_{ls}\) | train | PPL | BLEU | params | |
| steps | (dev) | (dev) | \(\times10^6\) | |||||||||
| base | 6 | 512 | 2048 | 8 | 64 | 64 | 0.1 | 0.1 | 100K | 4.92 | 25.8 | 65 |
| 1 | 512 | 512 | 5.29 | 24.9 | ||||||||
| 4 | 128 | 128 | 5.00 | 25.5 | ||||||||
| 16 | 32 | 32 | 4.91 | 25.8 | ||||||||
| 32 | 16 | 16 | 5.01 | 25.4 | ||||||||
| 16 | 5.16 | 25.1 | 58 | |||||||||
| 32 | 5.01 | 25.4 | 60 | |||||||||
| 2 | 6.11 | 23.7 | 36 | |||||||||
| 4 | 5.19 | 25.3 | 50 | |||||||||
| 8 | 4.88 | 25.5 | 80 | |||||||||
| 256 | 32 | 32 | 5.75 | 24.5 | 28 | |||||||
| 1024 | 128 | 128 | 4.66 | 26.0 | 168 | |||||||
| 1024 | 5.12 | 25.4 | 53 | |||||||||
| 4096 | 4.75 | 26.2 | 90 | |||||||||
| 0.0 | 5.77 | 24.6 | ||||||||||
| 0.2 | 4.95 | 25.5 | ||||||||||
| 0.0 | 4.67 | 25.3 | ||||||||||
| 0.2 | 5.47 | 25.7 | ||||||||||
| (E) | positional embedding instead of sinusoids | 4.92 | 25.7 | |||||||||
| big | 6 | 1024 | 4096 | 16 | 0.3 | 300K | 4.33 | 26.4 | 213 | |||
To evaluate the importance of different components of the Transformer, we varied our base model in different ways, measuring the change in performance on English-to-German translation on the development set, newstest2013. We used beam search as described in the previous section, but no checkpoint averaging. We present these results in Table 3.
In Table 3 rows (A), we vary the number of attention heads and the attention key and value dimensions, keeping the amount of computation constant, as described in Section 3.2.2. While single-head attention is 0.9 BLEU worse than the best setting, quality also drops off with too many heads.On the ablation: dropping to a single attention head costs 0.9 BLEU (substantial for translation). Going *past* the sweet spot also hurts. Eight heads turned out to be roughly optimal, but the curve is a U-shape — too few and the model can't capture multiple patterns; too many and each head is too narrow to learn anything useful on its own.
In Table 3 rows (B), we observe that reducing the attention key size \(d_k\) hurts model quality. This suggests that determining compatibility is not easy and that a more sophisticated compatibility function than dot product may be beneficial.An interesting ablation: when they shrank the key dimension d_k, translation quality dropped noticeably. Their speculation: plain dot products might be too blunt an instrument for deciding which words should attend to which. A more sophisticated compatibility function — maybe a small neural network scoring queries against keys — could work better. (Nobody's really replaced dot products in practice, but this was an early hint.) We further observe in rows (C) and (D) that, as expected, bigger models are better, and dropout is very helpful in avoiding over-fitting. In row (E) we replace our sinusoidal positional encoding with learned positional embeddings , and observe nearly identical results to the base model.They also tried swapping the sinusoidal position encoding for a learned one — just an embedding table indexed by position — and got nearly identical scores. The sinusoid story might be elegant, but on these benchmarks at these sentence lengths, the model doesn't actually care which scheme you use. Learned position embeddings have become more common in later models.
English Constituency Parsing
| Parser | Training | WSJ 23 F1 |
|---|---|---|
| Vinyals & Kaiser el al. (2014) | WSJ only, discriminative | 88.3 |
| Petrov et al. (2006) | WSJ only, discriminative | 90.4 |
| Zhu et al. (2013) | WSJ only, discriminative | 90.4 |
| Dyer et al. (2016) | WSJ only, discriminative | 91.7 |
| Transformer (4 layers) | WSJ only, discriminative | 91.3 |
| Zhu et al. (2013) | semi-supervised | 91.3 |
| Huang & Harper (2009) | semi-supervised | 91.3 |
| McClosky et al. (2006) | semi-supervised | 92.1 |
| Vinyals & Kaiser el al. (2014) | semi-supervised | 92.1 |
| Transformer (4 layers) | semi-supervised | 92.7 |
| Luong et al. (2015) | multi-task | 93.0 |
| Dyer et al. (2016) | generative | 93.3 |
To evaluate if the Transformer can generalize to other tasks we performed experiments on English constituency parsing. This task presents specific challenges: the output is subject to strong structural constraints and is significantly longer than the input. Furthermore, RNN sequence-to-sequence models have not been able to attain state-of-the-art results in small-data regimes .
We trained a 4-layer transformer with \(d_{model} = 1024\) on the Wall Street Journal (WSJ) portion of the Penn Treebank , about 40K training sentences. We also trained it in a semi-supervised setting, using the larger high-confidence and BerkleyParser corpora from with approximately 17M sentences . We used a vocabulary of 16K tokens for the WSJ only setting and a vocabulary of 32K tokens for the semi-supervised setting.
We performed only a small number of experiments to select the dropout, both attention and residual (section 5.4), learning rates and beam size on the Section 22 development set, all other parameters remained unchanged from the English-to-German base translation model. During inference, we increased the maximum output length to input length + \(300\). We used a beam size of \(21\) and \(\alpha=0.3\) for both WSJ only and the semi-supervised setting.
Our results in Table 4 show that despite the lack of task-specific tuning our model performs surprisingly well, yielding better results than all previously reported models with the exception of the Recurrent Neural Network GrammarFinally: was this specific to translation? They pointed the same architecture at *English constituency parsing* — producing a grammatical tree for each sentence — with almost no tweaking. It performed surprisingly well, better than nearly every prior system on that task. Good evidence the architecture generalizes beyond the problem it was designed for. .
In contrast to RNN sequence-to-sequence models , the Transformer outperforms the BerkeleyParser even when training only on the WSJ training set of 40K sentences.
Conclusion
In this work, we presented the Transformer, the first sequence transduction model based entirely on attention, replacing the recurrent layers most commonly used in encoder-decoder architectures with multi-headed self-attention.
For translation tasks, the Transformer can be trained significantly faster than architectures based on recurrent or convolutional layers. On both WMT 2014 English-to-German and WMT 2014 English-to-French translation tasks, we achieve a new state of the art. In the former task our best model outperforms even all previously reported ensembles.
We are excited about the future of attention-based models and plan to apply them to other tasks. We plan to extend the Transformer to problems involving input and output modalities other than text and to investigate local, restricted attention mechanisms to efficiently handle large inputs and outputs such as images, audio and video. Making generation less sequential is another research goals of ours.One loose thread: while *training* is now fully parallel, *generation* still isn't. When the Transformer produces a translation at inference time, it has to produce word 1, then word 2, then word 3 — each conditioned on the previous. Making generation less sequential is flagged as future work. (Several papers since have tried; it's still an open problem at the time of writing.)
The code we used to train and evaluate our models is available at https://github.com/tensorflow/tensor2tensor.
Acknowledgements
We are grateful to Nal Kalchbrenner and Stephan Gouws for their fruitful comments, corrections and inspiration.
10
Jimmy Lei Ba, Jamie Ryan Kiros, and Geoffrey E Hinton. Layer normalization. , 2016.
Dzmitry Bahdanau, Kyunghyun Cho, and Yoshua Bengio. Neural machine translation by jointly learning to align and translate. , abs/1409.0473, 2014.
Denny Britz, Anna Goldie, Minh-Thang Luong, and Quoc V. Le. Massive exploration of neural machine translation architectures. , abs/1703.03906, 2017.
Jianpeng Cheng, Li Dong, and Mirella Lapata. Long short-term memory-networks for machine reading. , 2016.
Kyunghyun Cho, Bart van Merrienboer, Caglar Gulcehre, Fethi Bougares, Holger Schwenk, and Yoshua Bengio. Learning phrase representations using rnn encoder-decoder for statistical machine translation. , abs/1406.1078, 2014.
Francois Chollet. Xception: Deep learning with depthwise separable convolutions. , 2016.
Junyoung Chung, Çaglar Gülçehre, Kyunghyun Cho, and Yoshua Bengio. Empirical evaluation of gated recurrent neural networks on sequence modeling. , abs/1412.3555, 2014.
Chris Dyer, Adhiguna Kuncoro, Miguel Ballesteros, and Noah A. Smith. Recurrent neural network grammars. In Proc. of NAACL, 2016.
Jonas Gehring, Michael Auli, David Grangier, Denis Yarats, and Yann N. Dauphin. Convolutional sequence to sequence learning. , 2017.
Alex Graves. Generating sequences with recurrent neural networks. , 2013.
Kaiming He, Xiangyu Zhang, Shaoqing Ren, and Jian Sun. Deep residual learning for image recognition. In Proceedings of the IEEE Conference on Computer Vision and Pattern Recognition, pages 770–778, 2016.
Sepp Hochreiter, Yoshua Bengio, Paolo Frasconi, and Jürgen Schmidhuber. Gradient flow in recurrent nets: the difficulty of learning long-term dependencies, 2001.
Sepp Hochreiter and Jürgen Schmidhuber. Long short-term memory. , 9(8):1735–1780, 1997.
Zhongqiang Huang and Mary Harper. Self-training PCFG grammars with latent annotations across languages. In Proceedings of the 2009 Conference on Empirical Methods in Natural Language Processing, pages 832–841. ACL, August 2009.
Rafal Jozefowicz, Oriol Vinyals, Mike Schuster, Noam Shazeer, and Yonghui Wu. Exploring the limits of language modeling. , 2016.
Łukasz Kaiser and Samy Bengio. Can active memory replace attention? In Advances in Neural Information Processing Systems, (NIPS), 2016.
Łukasz Kaiser and Ilya Sutskever. Neural GPUs learn algorithms. In International Conference on Learning Representations (ICLR), 2016.
Nal Kalchbrenner, Lasse Espeholt, Karen Simonyan, Aaron van den Oord, Alex Graves, and Koray Kavukcuoglu. Neural machine translation in linear time. , 2017.
Yoon Kim, Carl Denton, Luong Hoang, and Alexander M. Rush. Structured attention networks. In International Conference on Learning Representations, 2017.
Diederik Kingma and Jimmy Ba. Adam: A method for stochastic optimization. In ICLR, 2015.
Oleksii Kuchaiev and Boris Ginsburg. Factorization tricks for LSTM networks. , 2017.
Zhouhan Lin, Minwei Feng, Cicero Nogueira dos Santos, Mo Yu, Bing Xiang, Bowen Zhou, and Yoshua Bengio. A structured self-attentive sentence embedding. , 2017.
Minh-Thang Luong, Quoc V. Le, Ilya Sutskever, Oriol Vinyals, and Lukasz Kaiser. Multi-task sequence to sequence learning. , 2015.
Minh-Thang Luong, Hieu Pham, and Christopher D Manning. Effective approaches to attention-based neural machine translation. , 2015.
Mitchell P Marcus, Mary Ann Marcinkiewicz, and Beatrice Santorini. Building a large annotated corpus of english: The penn treebank. , 19(2):313–330, 1993.
David McClosky, Eugene Charniak, and Mark Johnson. Effective self-training for parsing. In Proceedings of the Human Language Technology Conference of the NAACL, Main Conference, pages 152–159. ACL, June 2006.
Ankur Parikh, Oscar Täckström, Dipanjan Das, and Jakob Uszkoreit. A decomposable attention model. In Empirical Methods in Natural Language Processing, 2016.
Romain Paulus, Caiming Xiong, and Richard Socher. A deep reinforced model for abstractive summarization. , 2017.
Slav Petrov, Leon Barrett, Romain Thibaux, and Dan Klein. Learning accurate, compact, and interpretable tree annotation. In Proceedings of the 21st International Conference on Computational Linguistics and 44th Annual Meeting of the ACL, pages 433–440. ACL, July 2006.
Ofir Press and Lior Wolf. Using the output embedding to improve language models. , 2016.
Rico Sennrich, Barry Haddow, and Alexandra Birch. Neural machine translation of rare words with subword units. , 2015.
Noam Shazeer, Azalia Mirhoseini, Krzysztof Maziarz, Andy Davis, Quoc Le, Geoffrey Hinton, and Jeff Dean. Outrageously large neural networks: The sparsely-gated mixture-of-experts layer. , 2017.
Nitish Srivastava, Geoffrey E Hinton, Alex Krizhevsky, Ilya Sutskever, and Ruslan Salakhutdinov. Dropout: a simple way to prevent neural networks from overfitting. , 15(1):1929–1958, 2014.
Sainbayar Sukhbaatar, Arthur Szlam, Jason Weston, and Rob Fergus. End-to-end memory networks. In C. Cortes, N. D. Lawrence, D. D. Lee, M. Sugiyama, and R. Garnett, editors, Advances in Neural Information Processing Systems 28, pages 2440–2448. Curran Associates, Inc., 2015.
Ilya Sutskever, Oriol Vinyals, and Quoc VV Le. Sequence to sequence learning with neural networks. In Advances in Neural Information Processing Systems, pages 3104–3112, 2014.
Christian Szegedy, Vincent Vanhoucke, Sergey Ioffe, Jonathon Shlens, and Zbigniew Wojna. Rethinking the inception architecture for computer vision. , abs/1512.00567, 2015.
Vinyals & Kaiser, Koo, Petrov, Sutskever, and Hinton. Grammar as a foreign language. In Advances in Neural Information Processing Systems, 2015.
Yonghui Wu, Mike Schuster, Zhifeng Chen, Quoc V Le, Mohammad Norouzi, Wolfgang Macherey, Maxim Krikun, Yuan Cao, Qin Gao, Klaus Macherey, et al. Google’s neural machine translation system: Bridging the gap between human and machine translation. , 2016.
Jie Zhou, Ying Cao, Xuguang Wang, Peng Li, and Wei Xu. Deep recurrent models with fast-forward connections for neural machine translation. , abs/1606.04199, 2016.
Muhua Zhu, Yue Zhang, Wenliang Chen, Min Zhang, and Jingbo Zhu. Fast and accurate shift-reduce constituent parsing. In Proceedings of the 51st Annual Meeting of the ACL (Volume 1: Long Papers), pages 434–443. ACL, August 2013.
Attention Visualizations